M2M-HMR
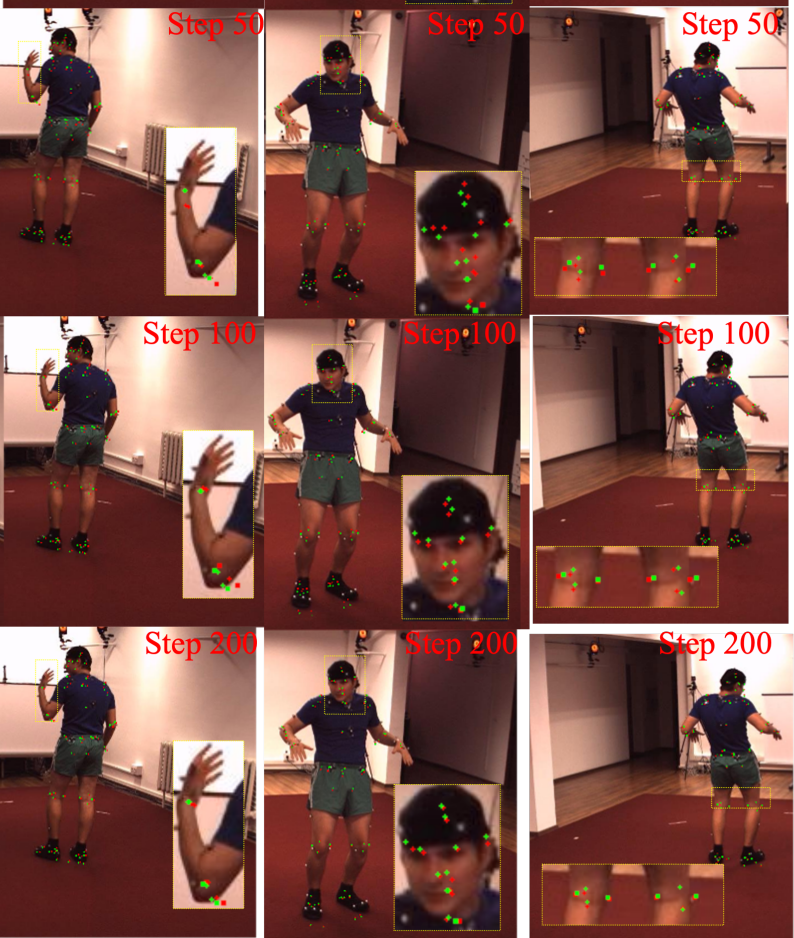
Monocular Models are Strong Learners for Multi-View Human Mesh Recovery
Applied Scientist II · Amazon Music
Scholar GitHub LinkedIn X Email
I'm an Applied Scientist II at Amazon Music, where I work on multimodal content understanding for music, including track and artist understanding across all genres, as well as sonics, sequencing, and recommendation, building LLM-based systems with LoRA fine-tuning and automated evaluators. I received my Ph.D. in Computer Science from the University of North Carolina at Charlotte in 2026, advised by Prof. Pu Wang in the GENIUS Lab. I was previously a Research Scientist Intern at Google's Extended Reality (AR/VR) team, and my work includes a U.S. Patent on 3D human pose and movement estimation from monocular images.
Research interests
3D Computer Vision·Digital Humans·Generative Motion·Diffusion Models·Multimodal Learning·Audio & Music Representation·Interactive XR
Open to research collaborations and opportunities. Reach me at usama.saleem7977@gmail.com.
Monocular Models are Strong Learners for Multi-View Human Mesh Recovery
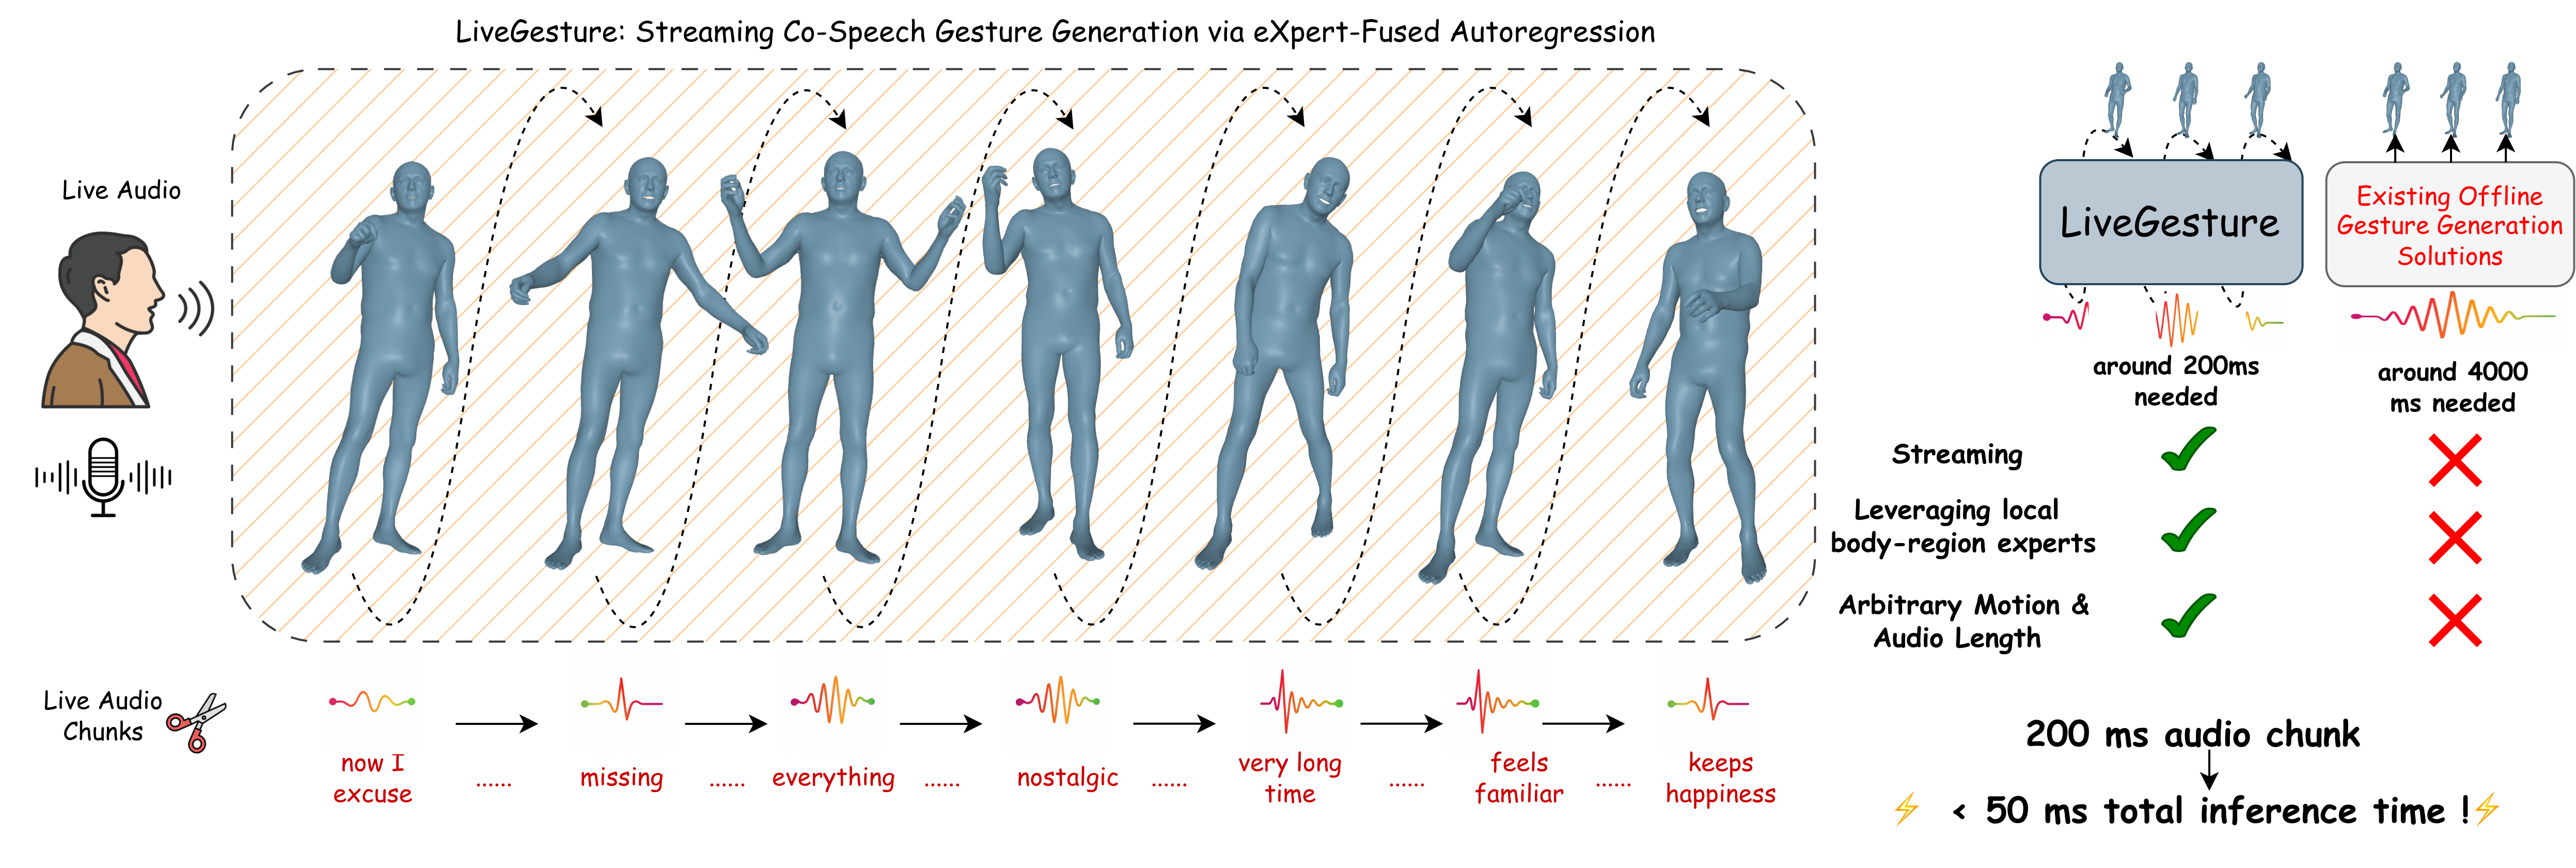
Streamable Co-Speech Gesture Generation Model
High-fidelity and Editable Dance Synthesis via Generative Masked Motion Prior
Generative Masked Modeling for Robust Hand Mesh Reconstruction in the Wild
Spatio-Temporal Control for Masked Motion Synthesis
Generative Human Mesh Recovery
Biomechanically-accurate 3D Pose Estimation from Monocular Videos
Bidirectional Autoregressive Motion Model
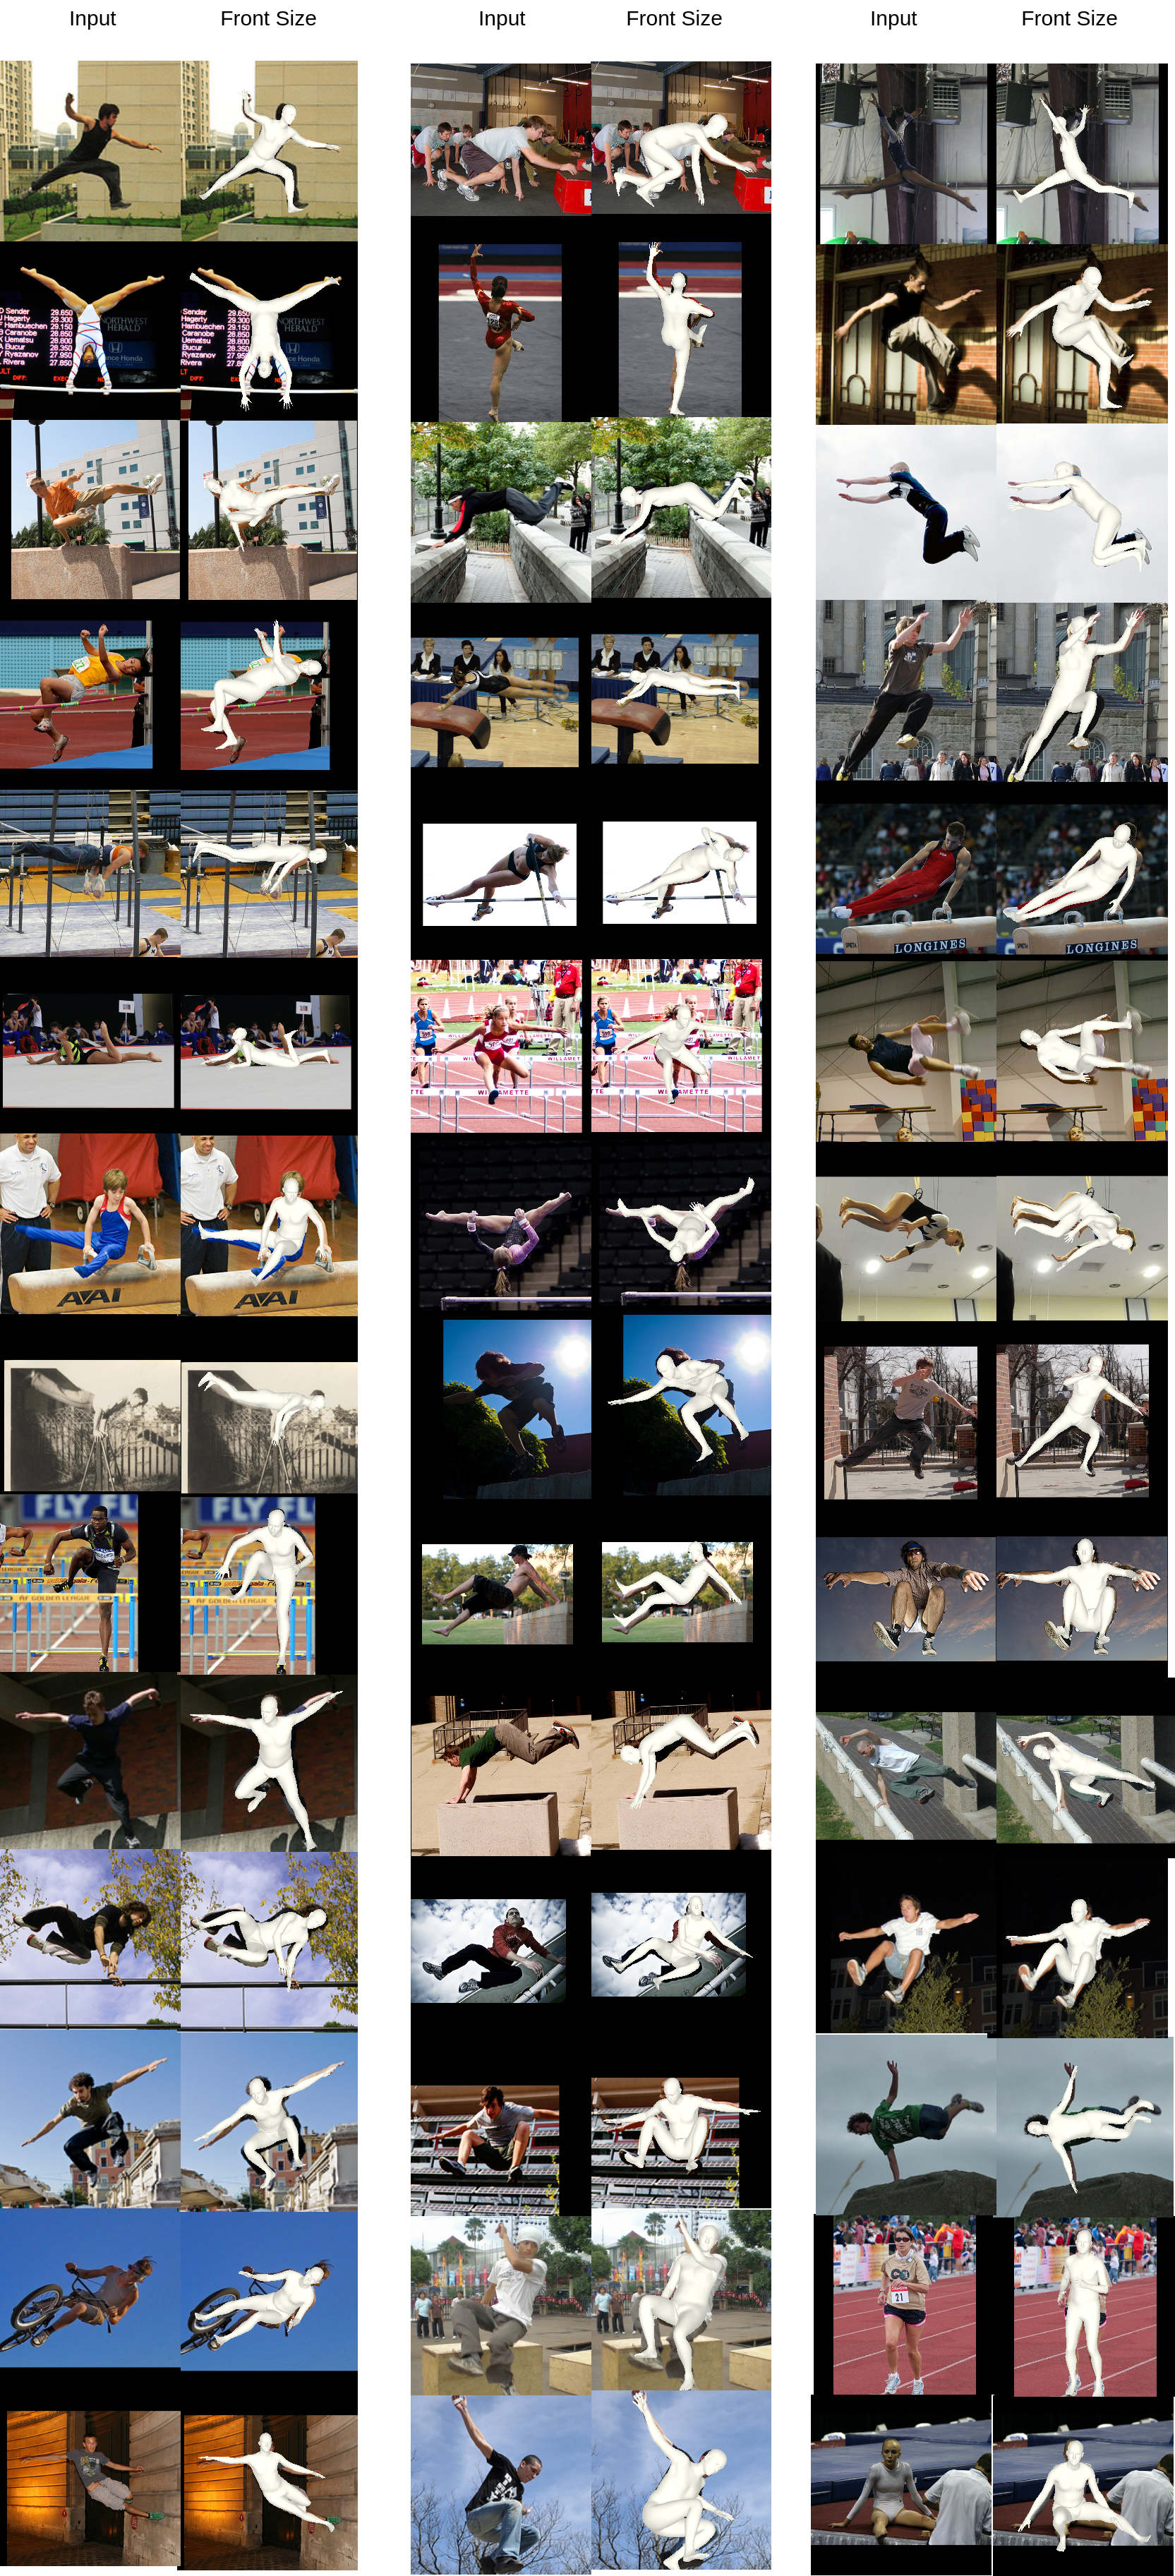
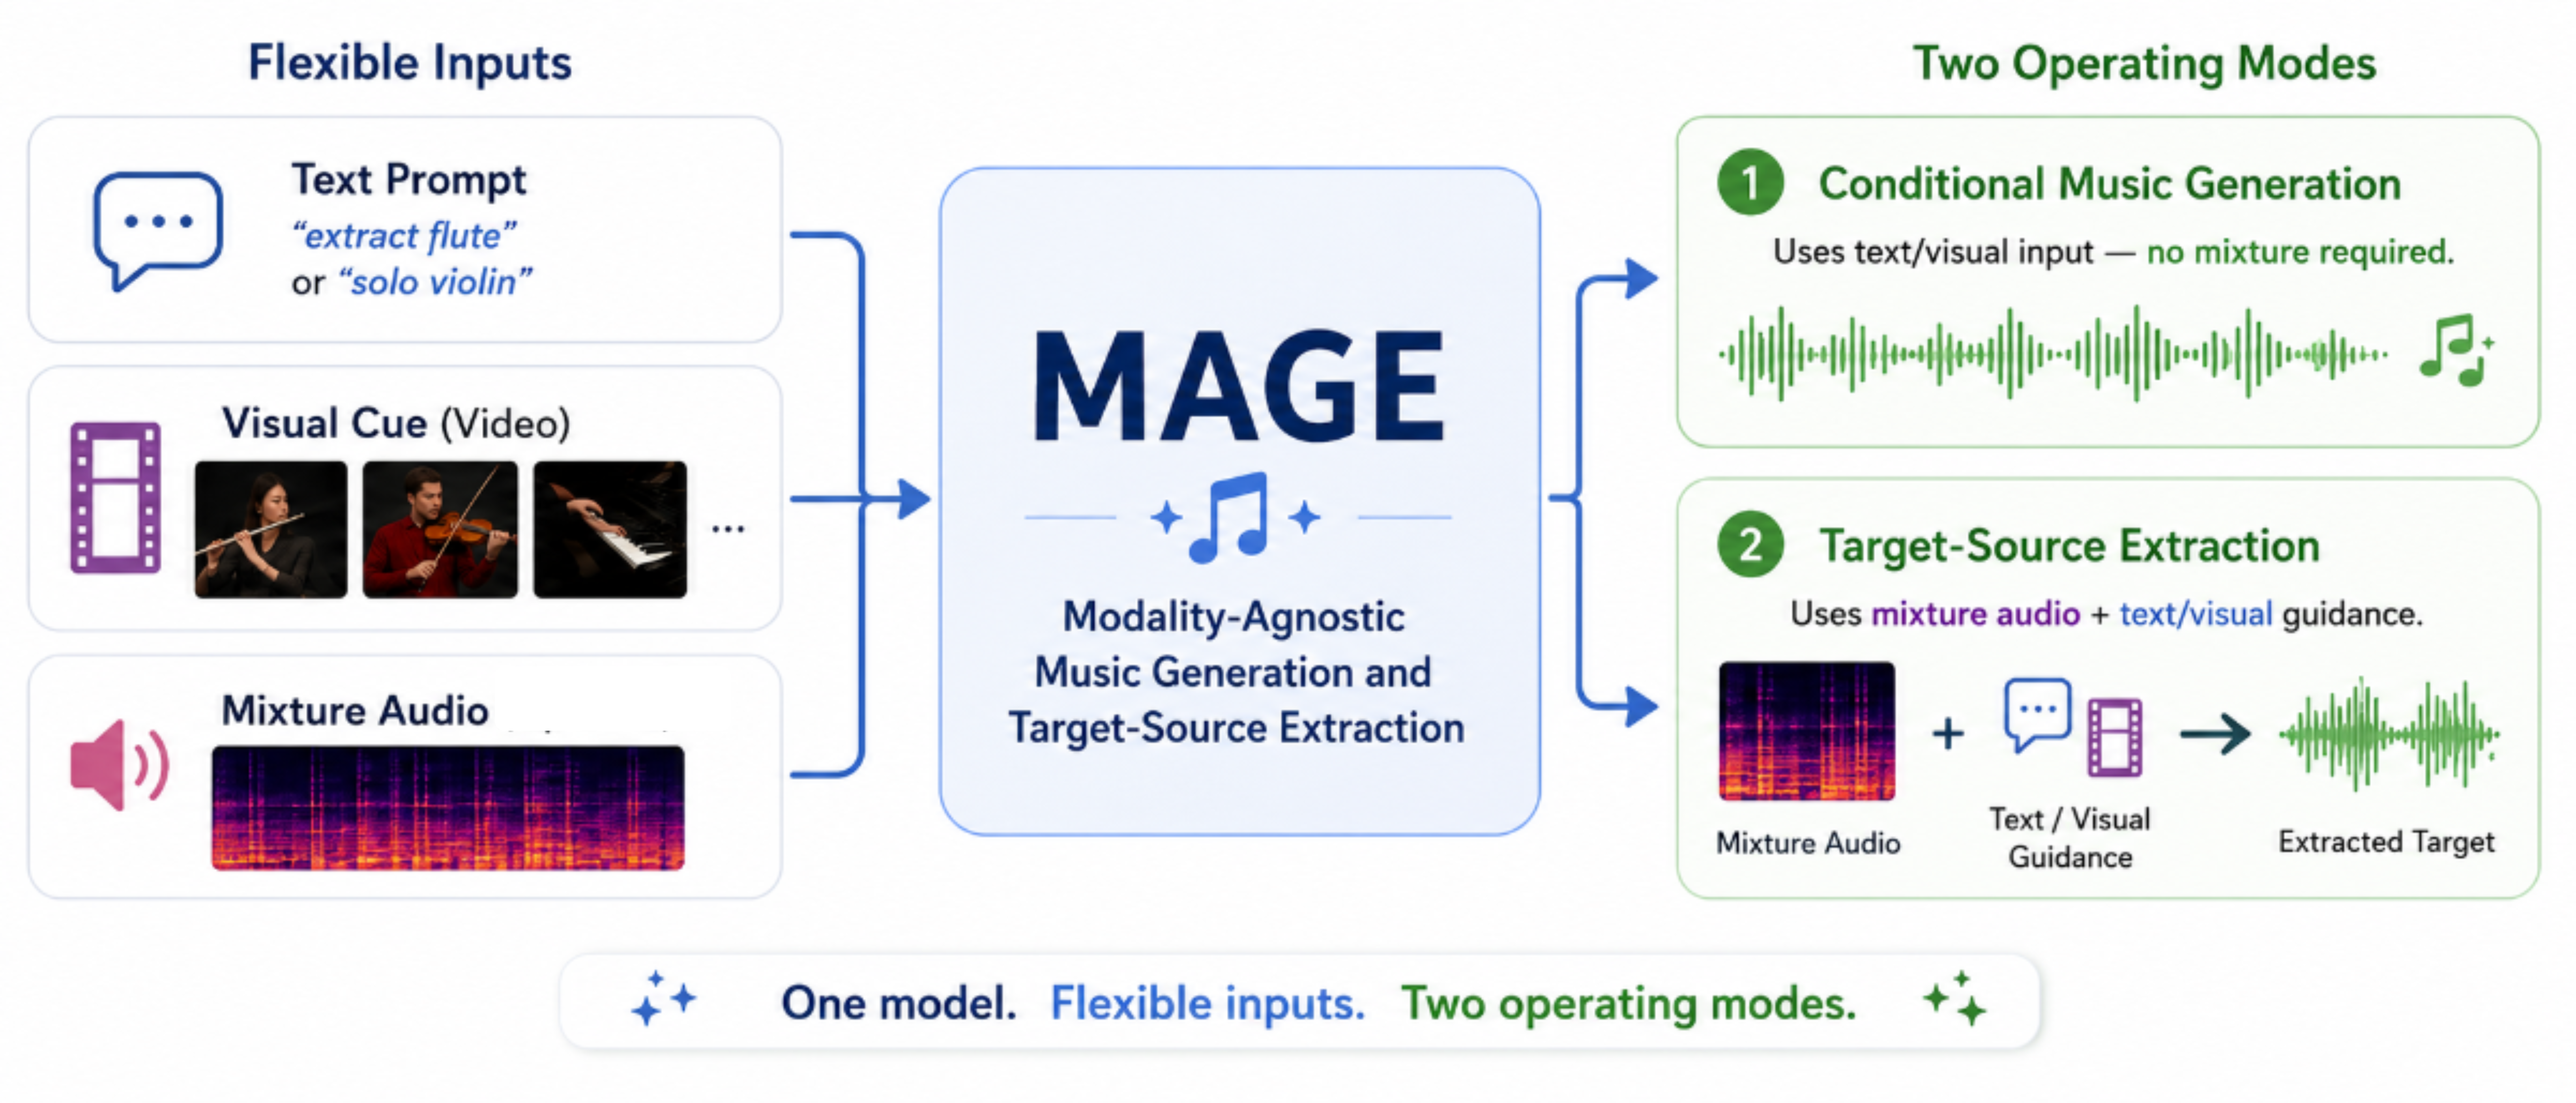
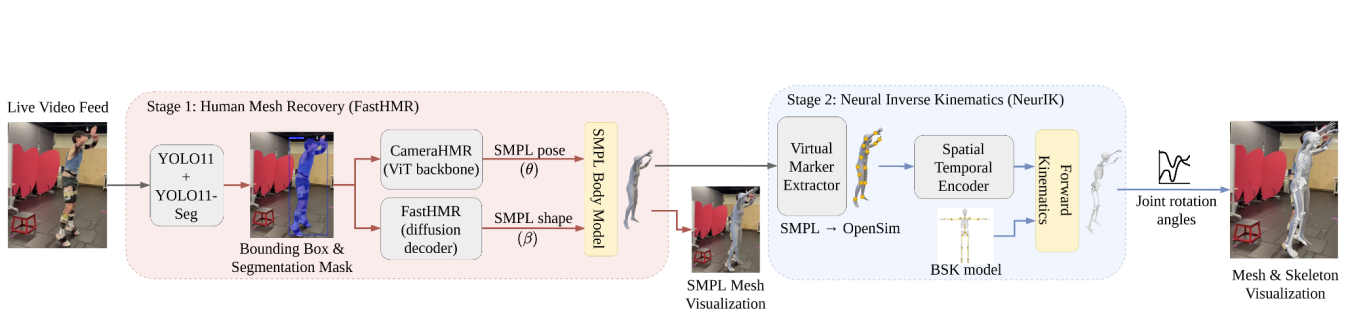
My research spans three areas: generative 3D human reconstruction, controllable motion synthesis, and multimodal audio generation and separation, with collaborations across Google DeepMind/XR, Amazon, Snapchat, and Lowe's.
Generative models that recover accurate 3D human pose and mesh directly from monocular images and video, replacing single-prediction regressors with masked and diffusion-based generation to handle depth ambiguity and occlusion. This spans full-body mesh recovery (GenHMR, M2M-HMR), hand mesh reconstruction in the wild (MaskHand), and biomechanically accurate pose estimation grounded in anatomical constraints (BioPose), alongside a U.S. patent on 3D pose and movement estimation from monocular images.
Generative frameworks for controllable, high-fidelity 3D human motion: streamable co-speech gesture generation with zero look-ahead (LiveGesture), editable dance synthesis via a generative masked motion prior (Walk Before You Dance), spatio-temporal control over masked motion synthesis (MaskControl, with Snapchat), and bidirectional autoregressive motion modeling (BAMM). I'm interested in how masking, tokenization, and diffusion jointly enable real-time, controllable generation.
Extending generative modeling beyond vision to audio and cross-modal settings, including a modality-agnostic framework for conditional music generation and mixture-grounded target-source extraction (MAGE), developed during a research internship at Google. At Amazon Music, I work on multimodal content understanding for music, including track and artist understanding across all genres, sonics, sequencing, and recommendation, using LLMs with LoRA fine-tuning and automated evaluators. I'm broadly interested in how the same generative principles (masking, tokenization, diffusion) transfer across modalities to build unified multimodal systems.